What is email A/B testing? An event campaign example
Email A/B testing compares versions of a message sent to different eligible recipients so you can learn whether one planned change appears to help. For an event campaign, that might mean testing two subject lines for the same registration announcement. It is a way to answer a narrow question, not a guarantee of more ticket sales. The useful result is often a clearer decision about the next email, including when the evidence is too weak to choose.
Boletolibre editorial team
Published
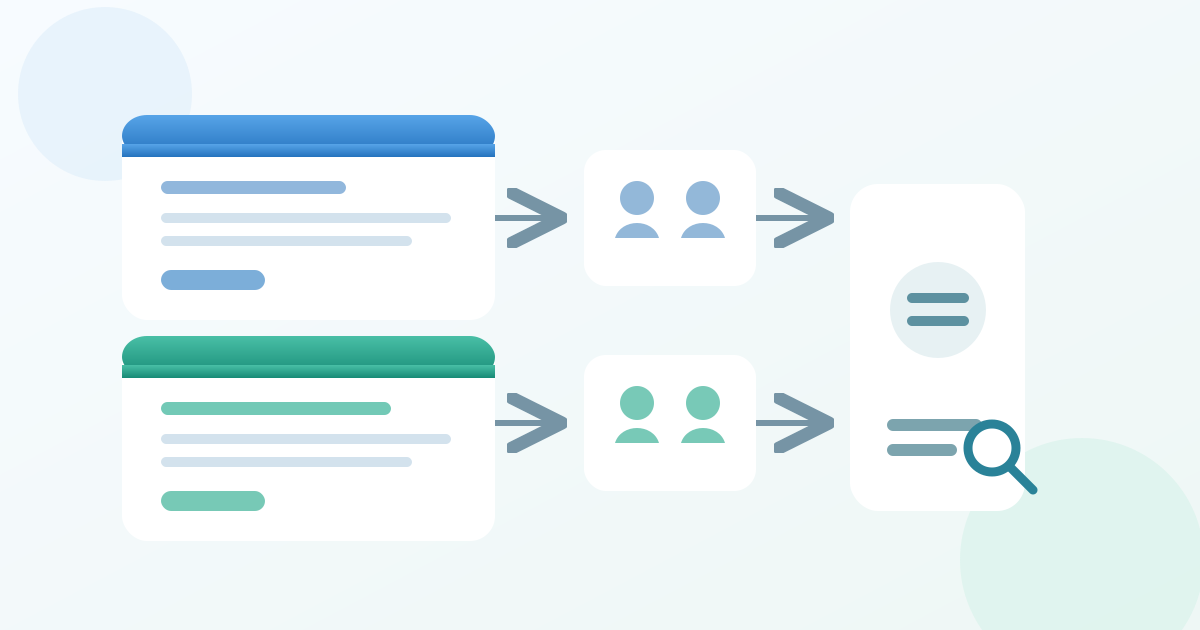
What an email A/B test actually compares
Start with one audience, one purpose and two versions called A and B. Keep the offer, approved event facts, destination and measurement window aligned. Change the element named in the hypothesis, such as subject line, sender name, body content or send time. The email service must be able to allocate eligible recipients between versions and report each version separately. Some services offer an automatic “winner”; that label only reflects the metric and rules configured in that service. It does not prove that every recipient prefers that version or that a different event will get the same result.[1]
- A pre-send QA check asks whether the email works and the facts are correct. An A/B test asks which of two acceptable choices performs better under a defined measure.
- A landing-page A/B test changes the destination page. Keep that as a separate experiment if the email is the variable you want to understand.
Choose a question worth answering
A useful question names a decision you can make after the send. For example: “Does a subject that states the registration deadline bring more qualified visits than one that names the keynote?” Both versions must still be truthful and appropriate for the same audience. A small wording preference may not justify a test if the registration link, language or core event details are still unapproved. Fix those issues first. Conversely, do not test urgent operational notices just to optimize engagement: send the accurate instruction promptly through the approved communication path.
- Suitable choices can include subject emphasis, the order of two confirmed benefits, or a call-to-action label that leads to the same live page.
- Keep price, availability, venue, accessibility information and other consequential facts consistent unless the specific fact is itself the approved subject of a controlled test.
Write the hypothesis before the variants
Record the audience, the single change, the expected direction and the reason it matters. “For people invited to [Event], a subject that names the registration action will produce more qualified clicks than a topic-led subject, because the next step is clearer” is testable. Write version A and version B in full, including preview text, so an unnoticed second change does not creep in. If both subject and body change, you will not know which change influenced the result. Keep the message useful in either version; A is not a deliberately weak control. Review both versions against the same source of approved event facts and send a real test email for production QA.[1]
- Hypothesis: audience + one altered element + primary outcome + reason.
- Control record: what stays identical, who approved the facts, and which destination will be used.
Make the comparison fair to recipients
Use the same eligibility rule for both versions: permission status, audience language, event interest and exclusions should be decided before assignment. Where the sender supports randomized A/B delivery, let that tool allocate recipients so the versions are not knowingly sent to different kinds of people. Check the provider’s current plan and test settings; A/B features, recipient allocation and automatic winner rules vary. Do not send both versions to the same person as a supposed comparison. For a multilingual campaign, compare within an appropriate language group or document the language mix in each arm; otherwise a translation difference can masquerade as an email effect.[1][2]
- Record the eligible audience and exclusions before launch, rather than redefining them after seeing a result.
- If available recipients are few, treat the test as a directional observation and avoid a confident universal conclusion.
Choose an outcome tied to the decision
Pick one primary outcome in advance and keep its definition the same for A and B. A subject-line experiment might use unique clicks on the registration link among successfully delivered messages, if the sender reports those counts. A completed registration is closer to the event goal, but only use it as the test outcome when you can reliably connect that completion to the assigned version without double-counting. An email click is not a ticket sale, and a ticket sold is not an attendee checked in. Note the denominator, reporting window and data source alongside each number. You can watch secondary signals such as unsubscribes or replies, but do not switch the winning rule after viewing the numbers.[1][3][4]
- Opens are a fragile primary measure because privacy features can preload tracking pixels; the reported open may not represent a person reading the message.
- Automated security and link-preview activity can also inflate click or open data. Review the sender’s filtering and treat a small apparent difference cautiously.
Run the send as an operational handoff
Before launch, have the event owner approve the audience, both versions and the measurement rule. Have the email operator confirm that assignment and reporting work in the chosen provider. Check the actual registration path in each version through ticket choice and confirmation, using the live event destination. If the public event page is on Boletolibre.com, use its actual URL as the destination and verify that path; this does not imply Boletolibre provides campaign testing. Set a decision time that leaves enough room for the observed outcome to occur before a time-sensitive event offer ends. Document who may pause the send if a fact, link or inventory changes. Follow the provider’s current instructions rather than assuming that every service can send a “winner” to the remainder.[2]
- Owner approval: facts, audience, version difference and stopping conditions.
- Operator approval: test configuration, destination, reporting export and send authorization.
Interpret a result without overstating it
At the planned review time, record for each version the assigned or delivered count, the primary-outcome count, the resulting rate and any missing data. Compare the same measure over the same window. A larger raw click total can simply reflect a larger delivered audience. If version B looks better, inspect whether it also brought useful traffic and whether the gap is large enough to matter for the next decision. Small audiences and small gaps can be inconclusive; “test again” is a valid decision. If price, stock, destination, schedule or audience eligibility changed during the test, flag the result as compromised rather than treating the platform’s winner badge as proof.[3][4]
- Keep the original hypothesis and the observed numbers together; do not rewrite the question to fit the outcome.
- Record a decision: adopt for a comparable next send, repeat with a cleaner test, or make no change.
A registration-email example
Suppose a conference organizer has one approved registration email and wants to know whether the subject should emphasize the program or the act of registering. Version A says “Explore the [Event] program”; version B says “Registration is open for [Event].” Both include the same approved preview, body, ticket destination and send context. The provider assigns eligible subscribers between versions. The team chooses unique registration-link clicks per delivered email as the primary measure and separately checks completed registrations only if a reliable version-to-order connection exists. If B gets more clicks but registration completion cannot be linked to the assigned version, the honest conclusion is about clicks, not sales. The next send can use B provisionally or repeat the test if the observed difference is slight.
- Do not copy these subjects into a live campaign without replacing the placeholder and checking current program, availability and permissions.
- If the event facts change during the run, record when and where; the example no longer represents a clean subject-only comparison.
What this test cannot establish
One send cannot reveal a timeless “best” subject for all events. It reflects this audience, offer, language, season and reporting setup. A comparison can also be distorted by uneven delivery, a broken destination, duplicate recipients, a change in ticket availability or tracking that treats automated visits as people. The test does not replace consent and unsubscribe checks, editorial review, or the production QA of both versions. If the email is a mandatory service notice or contains a correction, accuracy and timely delivery take priority over experimentation.
- Do not infer individual intent from an aggregate rate.
- Do not claim revenue lift from clicks or a registration lift from opens.
Document the test and the decision
Use the editable worksheet to keep the hypothesis, audience rule, approved copy, destination, primary metric, observed counts and final decision in one handoff. It is an English working template; adapt the fields to the provider and translate the final email for each audience language. The worksheet deliberately includes a “no conclusion” option so a small or disrupted test still produces a useful record.
Download the email A/B test design and decision worksheet (Markdown, English)
Sources and further reading
- About A/B TestsMailchimp · Accessed
- Create an A/B TestMailchimp · Accessed
- Apple Mail Privacy Protection FAQsMailchimp · Accessed
- About Bot Activity and Bot FilteringMailchimp · Accessed